
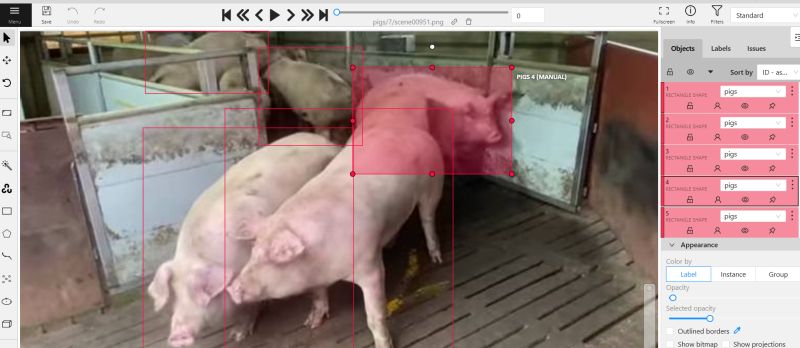
In 2026, data labeling remains one of the most critical factors in the success of machine learning projects.
Even the most advanced models depend on high-quality, well-structured data. Poor labeling leads to inaccurate predictions, increased costs, and longer development cycles — while precise annotation directly improves model performance and reliability.
As AI adoption grows, companies are paying more attention to scalable labeling processes, quality control, and the right balance between automation and human expertise. If you're building or scaling ML products, investing in data quality is no longer optional — it's a competitive advantage.
👉 Read the full article here: https://clck.ru/3TKBY6